Function Description
Copies a variable or an immediate for multiple times and fill it in the vector (PAR indicates the number of elements that can be processed by the Vector Unit in one iteration.):
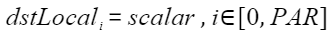
Function Prototype
Computation of the first n data elements of a tensor:
template <typename T>
void Duplicate(const LocalTensor<T>& dstLocal, const T& scalarValue, const int32_t& calCount)
Parameters
Table 1 Parameters
| Parameter | Input/Output | Description |
|---|---|---|
| dstLocal | Output | Destination operand. The type is LocalTensor, and the supported TPosition is VECIN, VECCALC, or VECOUT. The start address of the LocalTensor must be 32-byte aligned. For Kirin 9020, Kirin 9030, and Kirin X90 series processors, the supported data types include uint8, int8, uint16_t, int16_t, half, uint32_t, int32_t, float16, and float. |
| scalarValue | Input | A variable or an immediate, for the source operand to be copied. The data type must be the same as that of the element in dstLocal. |
| calCount | Input | Number of elements of the input data. |
Supported Models
Kirin 9020 series processors
Kirin 9030 series processors
Kirin X90 series processors
Precautions
For details about the alignment requirements of the operand address offset, see General Constraints.
Ensure that the immediate data does not exceed the size range corresponding to the element data type in dstLocal.
Calling Example
This example shows only part of the code used in the computation process (Compute). To run the sample code, use it to replace the bold code snippet of the Compute function in Sample Template.
Example of computing the first n data elements of a tensor:
half inputVal(18.0);
AscendC::Duplicate<half>(dstLocal, inputVal, srcDataSize);
An example of the result is as follows:
Input: [0 1.0 2.0... 254.0 255.0] // The input data is not concerned and will be overwritten by Duplicate.
Output: [18.0 18.0 18.0... 18.0 18.0]
Sample Template
#include "kernel_operator.h"
 class KernelDuplicate {
 public:
     __aicore__ inline KernelDuplicate() {}
     __aicore__ inline void Init(__gm__ uint8_t* src, __gm__ uint8_t* dstGm)
     {
         srcGlobal.SetGlobalBuffer((__gm__ half*)src);
         dstGlobal.SetGlobalBuffer((__gm__ half*)dstGm);
         pipe.InitBuffer(inQueueSrc, 1, srcDataSize * sizeof(half));
         pipe.InitBuffer(outQueueDst, 1, dstDataSize * sizeof(half));
     }
     __aicore__ inline void Process()
     {
         CopyIn();
         Compute();
         CopyOut();
     }
 private:
     __aicore__ inline void CopyIn()
     {
         AscendC::LocalTensor<half> srcLocal = inQueueSrc.AllocTensor<half>();
         AscendC::DataCopy(srcLocal, srcGlobal, srcDataSize);
         inQueueSrc.EnQue(srcLocal);
     }
     __aicore__ inline void Compute()
     {
         AscendC::LocalTensor<half> srcLocal = inQueueSrc.DeQue<half>();
         AscendC::LocalTensor<half> dstLocal = outQueueDst.AllocTensor<half>();
         **half inputVal(18.0);**
         **AscendC::Duplicate<half>(dstLocal, inputVal, srcDataSize);**
         outQueueDst.EnQue<half>(dstLocal);
         inQueueSrc.FreeTensor(srcLocal);
     }
     __aicore__ inline void CopyOut()
     {
         AscendC::LocalTensor<half> dstLocal = outQueueDst.DeQue<half>();
         AscendC::DataCopy(dstGlobal, dstLocal, dstDataSize);
         outQueueDst.FreeTensor(dstLocal);
     }
 private:
     AscendC::TPipe pipe;
     AscendC::TQue<AscendC::QuePosition::VECIN, 1> inQueueSrc;
     AscendC::TQue<AscendC::QuePosition::VECOUT, 1> outQueueDst;
     AscendC::GlobalTensor<half> srcGlobal, dstGlobal;
     int srcDataSize = 256;
     int dstDataSize = 256;
 };
 extern "C" __global__ __aicore__ void duplicate_kernel(__gm__ uint8_t* src, __gm__ uint8_t* dstGm)
 {
     KernelDuplicate op;
     op.Init(src, dstGm);
     op.Process();
 }