Overview
Performance optimization is a systematic process of improving the running speed, resource utilization, and response time of apps. It enables better app performance and stability. In the digital era, as apps grow in complexity and scale, tuning becomes increasingly critical. Effective tuning not only makes apps run more efficiently but also enhances stability, increases efficiency, and reduces resource waste, thereby improving user experience. Therefore, it is essential for developers to be well-versed in tuning techniques and familiar with the tools commonly used in the process.
The tuning process usually involves reproducing an on-site problem, analyzing the problem, determining the solution, and testing the performance. Reproducing an on-site problem refers to re-creating a problem in a specific scenario for better analysis and solution. Analyzing the problem is to deeply analyze the performance bottlenecks and root causes of the app, providing guidance for subsequent optimizations. Determining the solution is to work out a specific optimization solution and measures based on the problem analysis result. Testing the performance is a key step to verify the effectiveness of the tuning efforts. You can evaluate the improvements by testing the optimized app.
Some common tools can be used to achieve effective tuning. For example, DevEco Profiler can monitor app performance metrics and record traces. It enables you to analyze trace data and detect performance bottlenecks in the code, achieving optimized performance.
This topic describes the tuning methods and common tools, which help you to better analyze and solve performance issues in apps, improve user experience, and achieve efficient and stable running of apps.
In daily development, you need to pay attention to metrics such as completion latency, touch response latency, and scrolling response latency. More details are provided in Performance Experience Design.
Tuning Analysis
Tuning analysis plays a key role in app optimization, helping you identify issues, locate bottlenecks, and improve system performance. The specific method is as follows:
- Reproduce an on-site problem, which is the first step of tuning analysis. You can reproduce issues such as errors and frame freezing to confirm the problem's symptom and performance bottlenecks, and better understand and locate the issues, providing information for subsequent analysis.
- Analyze the problem, which is a key step during the tuning process. After confirming the symptom, you need to refer to observable data and further diagnose the problem of the app. Through systematic analysis, you can locate root causes of the problem, which lays a foundation for subsequent optimizations.
- Determine the solution. With the root causes identified, it is time to craft targeted solutions. This includes revisiting the codebase and finding an appropriate solution based on the service scenario and API.
- Test the performance, which is the last step to verify the tuning result. Test the optimized app to ensure that the performance improvement is effective. The performance test helps you evaluate the improvements, detect potential problems, and further optimize the app performance.
Tuning analysis is a crucial step in app optimization. Through the preceding procedure, you can identify and solve app performance issues, improving the efficiency and stability of apps.
[h2]DevEco Profiler
Provided by DevEco Studio, DevEco Profiler helps you identify performance problems in your app. It offers the following scenario-based optimization tools:
- Launch Profiler: analyzes performance issues in each phase of the startup process of an app or a service, including the time consumption and the running status of core threads, helping you identify the causes of slow startup.
- Frame Profiler: analyzes the causes of frame freezing and frame loss in apps or services by recording the GPU data and displaying the frame data of each process in the sub-lanes. This tool can also record and parse traces to analyze app performance and bottlenecks and provide an optimization solution. For details, see Trace Data Description.
- Time Profiler: displays call stack status in hotspot areas based on CPU usage and process time analysis and provides redirection to related code when apps or services are running, enabling you to optimize code more conveniently.
- Allocation Profiler: monitors the memory usage of apps or services in real time. You can use this tool to identify issues that may cause app freezing, memory leaks, or memory jitter.
- Snapshot Profiler: analyzes the memory usage of apps by recording the memory snapshots of running apps, providing a quick view of the memory usage and memory usage details of the apps at a specific time.
- CPU Profiler: monitors the CPU usage of apps and provides performance sampling and analysis methods for you. This tool can also obtain the execution time of functions at each layer of the call stacks without instrumentation and display the execution time on the timeline.
- ArkWeb analysis tool: DevEco Profiler provides an ArkWeb analysis template to allow you to pinpoint the phase where issues occur based on key trace points in the ArkWeb execution process.
- Network analysis tool: DevEco Profiler provides a network template to help you inspect the HTTP stack network information during app running, including the request segment duration and request content, facilitating network tuning.
Other common performance tuning tools include HiDumper and SmartPerf.
- HiDumper is a system information acquisition utility provided for developers and testers to analyze and locate problems. During app development, you can use the HiDumper command line tool to obtain the UI component tree information, together with graphical tools such as ArkUI Inspector to locate layout performance problems. This command line tool can also obtain system data such as the memory and CPU usage for evaluating app performance.
- SmartPerf is a performance and power consumption tuning utility that can be used to deeply explore and display data in a fine-grained manner. It can collect data such as CPU scheduling, frequency, process/thread time slices, heap memory, and frame rate, and clearly present the data through lane graphs. In addition, SmartPerf analyzes data in a visualized manner through the GUI. Currently, this tool provides five analysis templates: frame rate analysis, CPU/thread scheduling analysis, app launch analysis, TaskPool analysis, and animation analysis.

DevEco Profiler does not support emulators.
[h2]ArkUI Inspector
Introduction
You can use Inspector bidirectional preview to view the component layout of the app on a real device via DevEco Studio. By viewing the UI status after multiple operations, you can quickly analyze and locate issues such as status variables, component nesting layers, and UI layout problems.
Usage
For details, see:
Trace Data Description
The DFX subsystem of HarmonyOS provides performance traces for the app framework and core modules of the system. Each trace records the task execution time, formatted data at runtime, and process or thread information. You can use the frame of DevEco Studio to parse traces and identify key rendering processes in a lane graph.
[h2]Thread State Transition Process
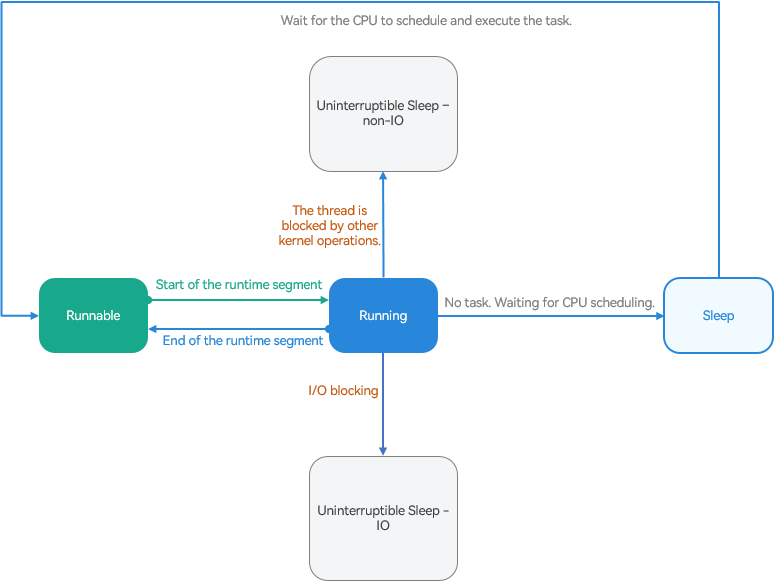
In HarmonyOS, thread states recorded by trace are classified into Running, Runnable, Sleep, Uninterruptible Sleep - IO, and Uninterruptible Sleep - non IO. The following figure shows the state transition.
[h2]Identifying Thread States Based on the Trace Information
Different colors are used in the traces to identify different thread states. Each method is provided with a corresponding thread state to identify the current thread state. By viewing the thread state, you can analyze the current performance bottleneck.
(1) Running
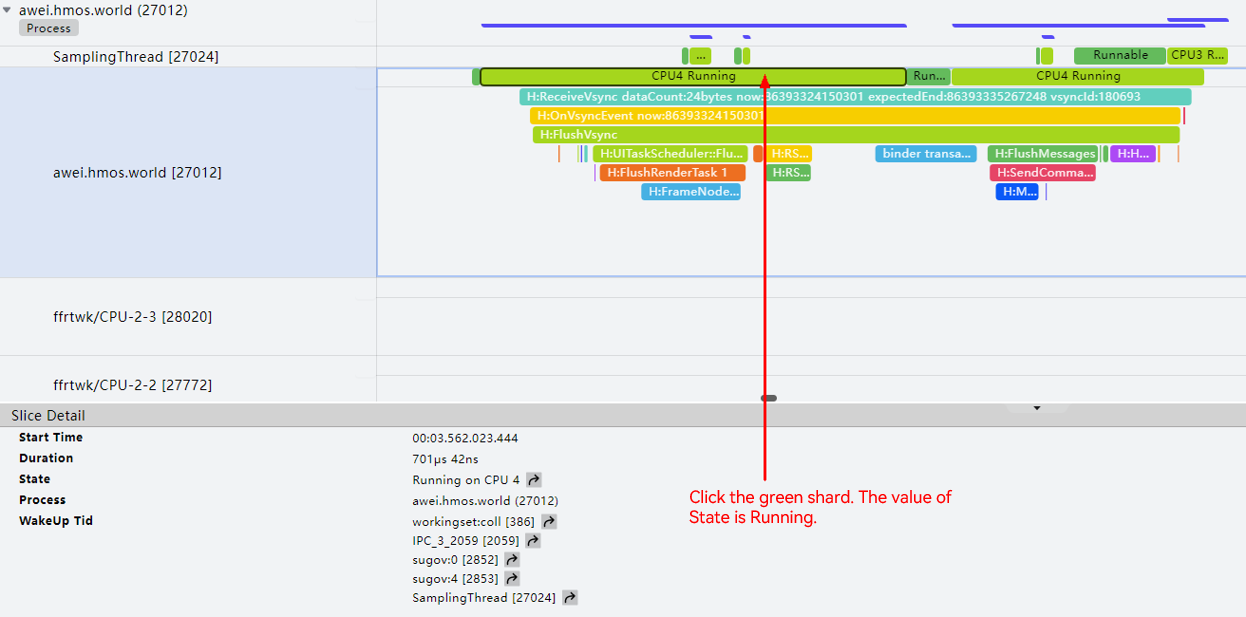
Running: indicates that only threads in the Running state can run on the CPU. Multiple threads may be executable at the same time. The task_struct structure of these threads is placed in the executable queue of the corresponding CPU (one thread can appear in the executable queue of only one CPU). From the executable queue of each CPU, the scheduler selects a thread to run on the CPU.
(2) Runnable
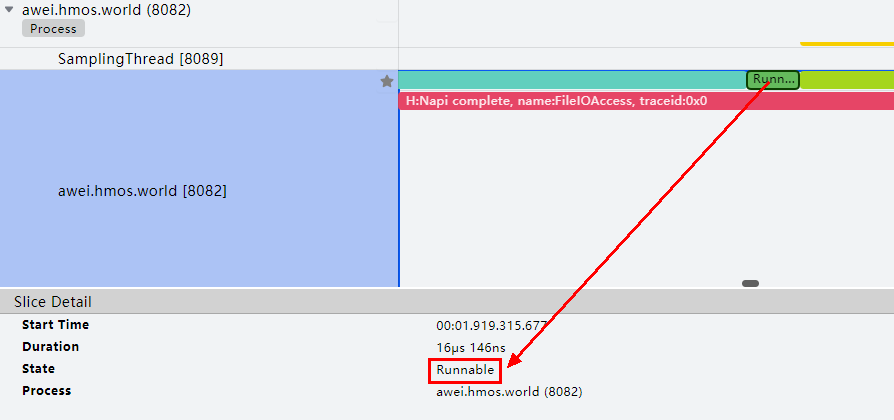
Runnable: indicates that a thread can run but is waiting for CPU scheduling. The longer the Runnable state lasts, the busier the CPU scheduling is, and the task has not been processed promptly.
(3) Sleep
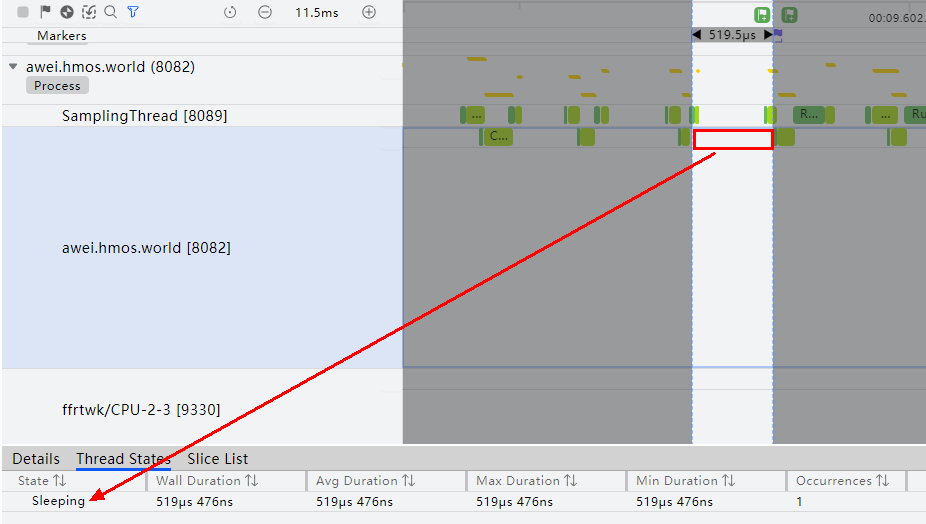
Sleep: indicates that the thread is not working. This could be because the thread is blocked on a mutex or waiting for an operation to complete, often in the context of event-driven operations.
(4) Uninterruptible Sleep (IO)
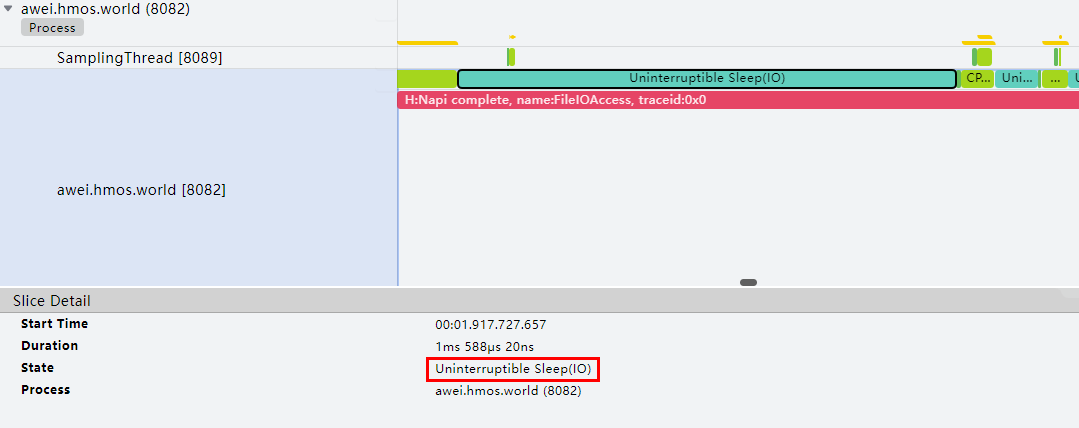
Uninterruptible Sleep (IO): indicates that the thread is blocked in the I/O operations or waits for the disk operation to complete. When the system memory is low, a page fault may be triggered during memory allocation, leading to a large number of uninterruptible sleep states. In the page cache linked list of the Linux system, some pages are not ready sometimes (that is, the contents in the disk have not been fully read). At this time, a page fault occurs when a user accesses the page.
(5) Uninterruptible Sleep (non-IO)
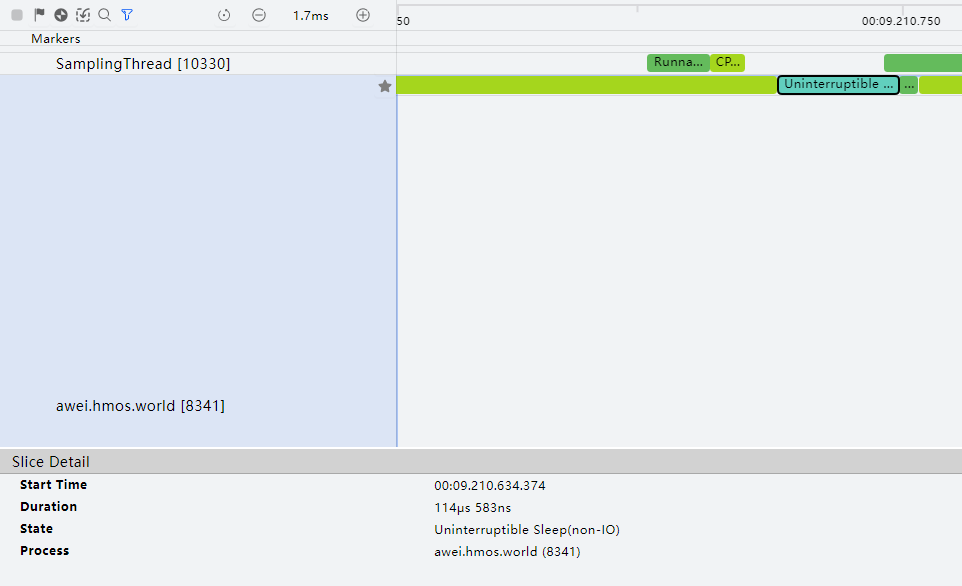
Uninterruptible Sleep (non-IO): indicates that the thread is blocked on another kernel operations (such as memory management). The thread is in the kernel mode, which is normal in some cases and needs further analysis in other cases.
[h2]Rendering Process
In HarmonyOS, the graphics subsystem uses a unified rendering mode, following the typical pipeline mode. For example, if the refresh rate is 60 Hz, the Vsync period is 16.7 ms; if the refresh rate is 90 Hz, the Vsync period is 11.1 ms; if the refresh rate is 120 Hz, the Vsync period is 8.3 ms.
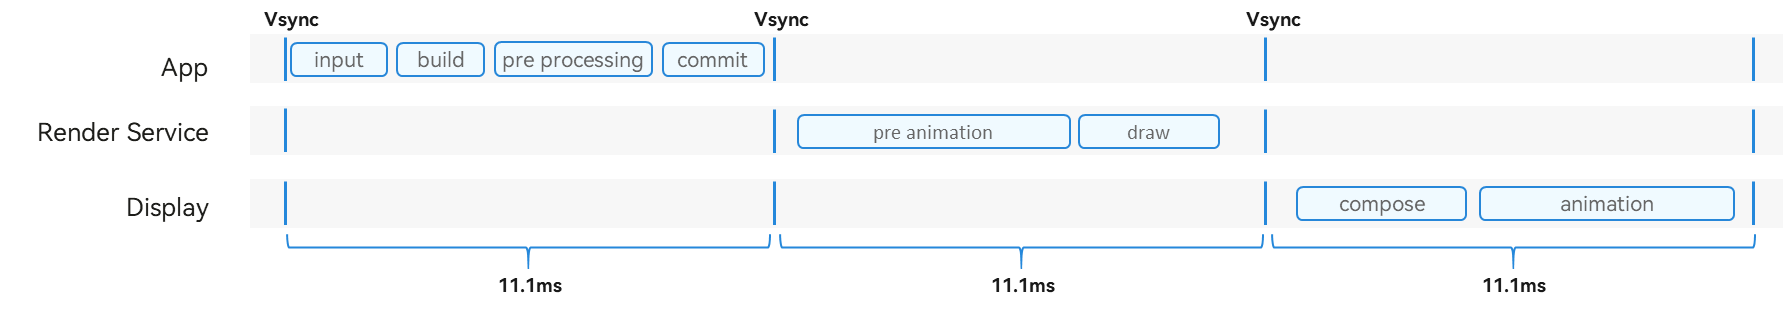
In the rendering process, the app responds to input events, such as screen touches, processes the events, and submits the processed events to Render Service. Render Service coordinates resources such as the GPU to carry out the rendering tasks and presents the final image on the display.
- The app processes user interactions like screen taps and generates a data structure that describes the UI. The data structure includes the position, size, resources, drawing instructions, and animation attributes of UI elements.
- Render Service is a module responsible for drawing UI content in the graphics stack. It connects to the ArkUI framework to support UI display of ArkUI apps, including UI elements such as components and animations. The RenderThread of Render Service triggers UI drawing in the Vsync signal. The drawing process consists of three phases: animation, drawing, and submission.
- Display is an abstract concept of a screen. It can be a physical or virtual display.
The following figure shows the rendering process on the app. By learning about the ArkUI rendering process, you can better locate freezing issues within the app.

- Animation: indicates the animation phase. The corresponding FrameNode node is modified to trigger dirty region flags. In specific scenarios, the ETS code on the user side is executed to implement custom animation.
- Events: indicates the event processing phase, for example, gesture event processing. During gesture processing, the FrameNode node is modified to trigger dirty region flags. In specific scenarios, the ETS code on the user side is executed to implement custom events.
- UpdateUI: updates the state of a custom component (a component decorated with @Component) to be re-created when it is initially created and mounted or when there are state variable changes. When the next Vsync signal arrives, the re-creation process is initiated to generate the corresponding component tree structure and tasks for modifying the attribute style.
- Measure: executes related size calculation tasks by the layout wrapper.
- Layout: executes related layout tasks by the layout wrapper.
- Render: executes related drawing tasks by the drawing task wrapper. After the execution is complete, the RSNode drawing is marked and updated.
- SendMessage: requests to update the drawing page.
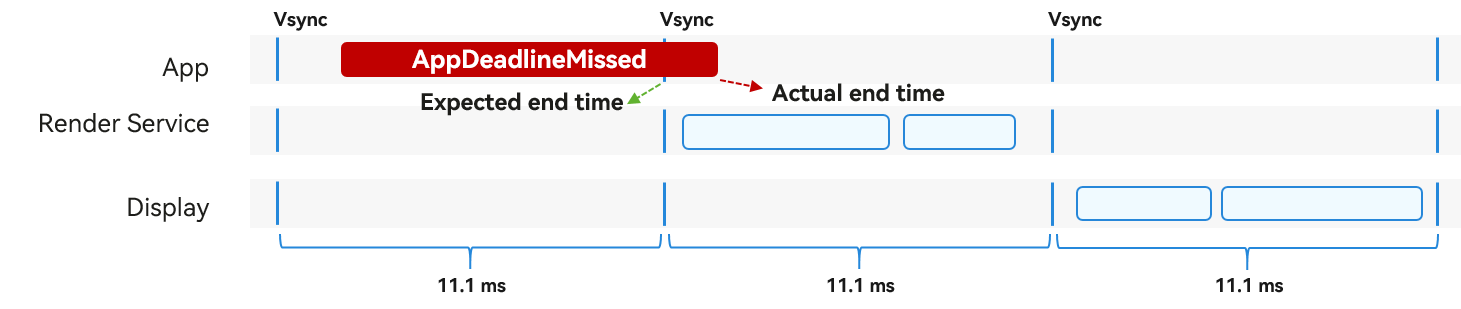
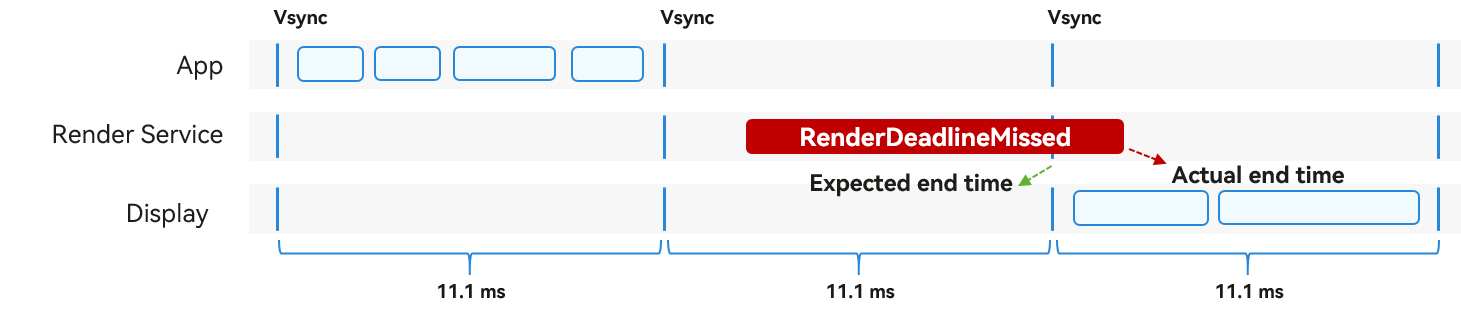
Throughout the entire process, both the app side and the Render Service side can encounter frame freezing, resulting in frame loss that end users can notice. These two situations are called AppDeadlineMissed and RenderDeadlineMissed, respectively. AppDeadlineMissed is usually caused by inefficient app logic processing code, whereas RenderDeadlineMissed may be caused by complex UI structures or high GPU loads. The two fault models can be viewed through the frame template. The following figures show the fault models.
[h2]Identifying Key Rendering Processes Using Traces
The following figure shows typical traces used by the UI backend engine in the rendering process of a frame.
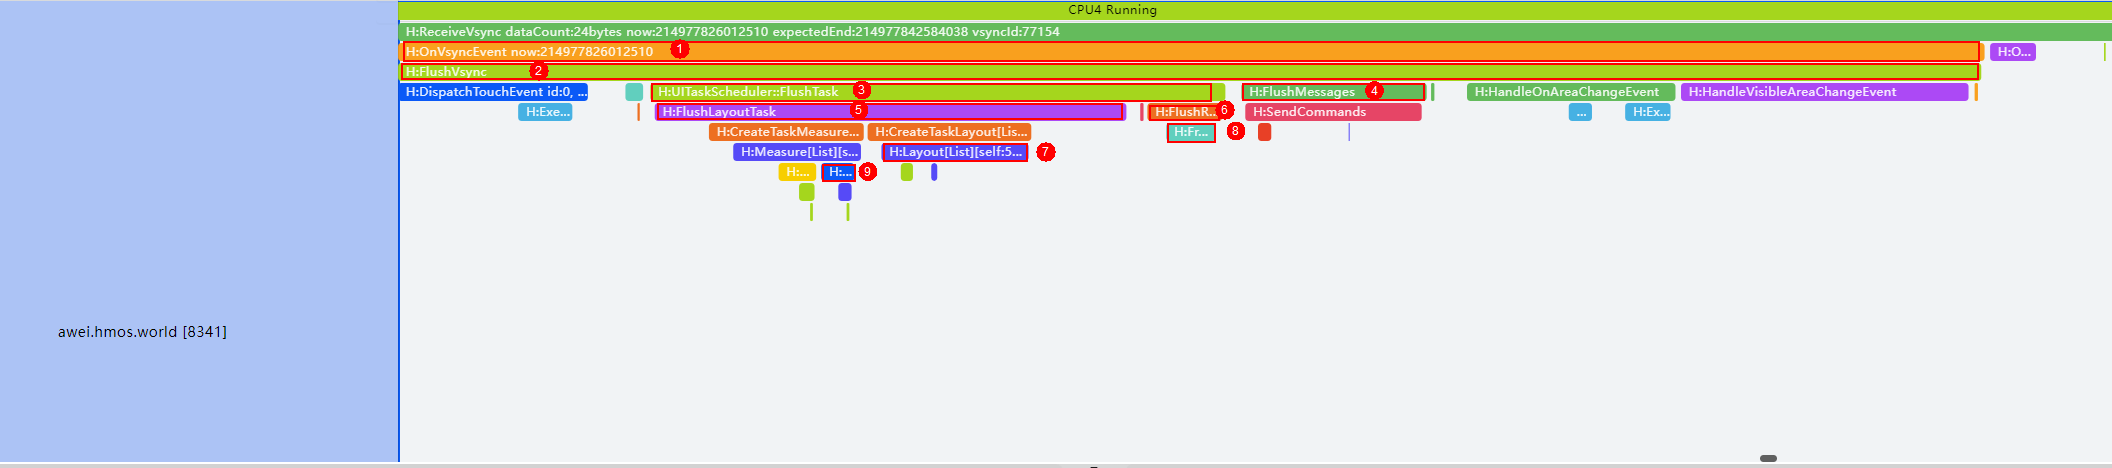
The following table describes each part of a trace.
No. | Trace | Parameter | Description |
|---|---|---|---|
1 | OnVsyncEvent now:%" PRIu64 " | Current timestamp, in nanoseconds. | Starts the rendering process after the Vsync signal is received. |
2 | FlushVsync | Refreshes the view synchronization events, including recording frame information, refreshing tasks, drawing and rendering the context, and processing user input. | |
3 | UITaskScheduler::FlushTask | Refreshes the UI, including the layout, rendering, and animation. | |
4 | FlushMessages | Sends a message to instruct the graphics side to perform rendering. | |
5 | FlushLayoutTask | Executes the layout task. | |
6 | FlushRenderTask %zu | Number of nodes to be rendered on the current page. | Executes the rendering task. |
7 | Layout | Lays out the nodes. | |
8 | FrameNode::RenderTask | Executes a single rendering task. | |
9 | ListLayoutAlgorithm::MeasureListItem:%d | Index of the current list item. | Calculates the layout size of the list item. |
Render Service in the graphics subsystem is responsible for drawing UI content, processing unified rendering tasks from apps, combining layers of different apps, and sending them for display. In each Vsync period, Render Service first processes instructions from apps, including adding, deleting, and modifying rendering tree nodes. It then performs animation calculation and occlusion calculation to update the unified rendering tree. After that, it draws the rendering tree, preprocesses each node, calculates the absolute position and dirty areas, and draws the dirty areas. The hardware synthesizer is preferentially used for drawing. If the hardware synthesizer cannot be used, the GPU is used for redrawing. All results are stored in the screen buffer and then sent for display.
The following figure shows a trace lane graph when the Vsync signal is refreshed.
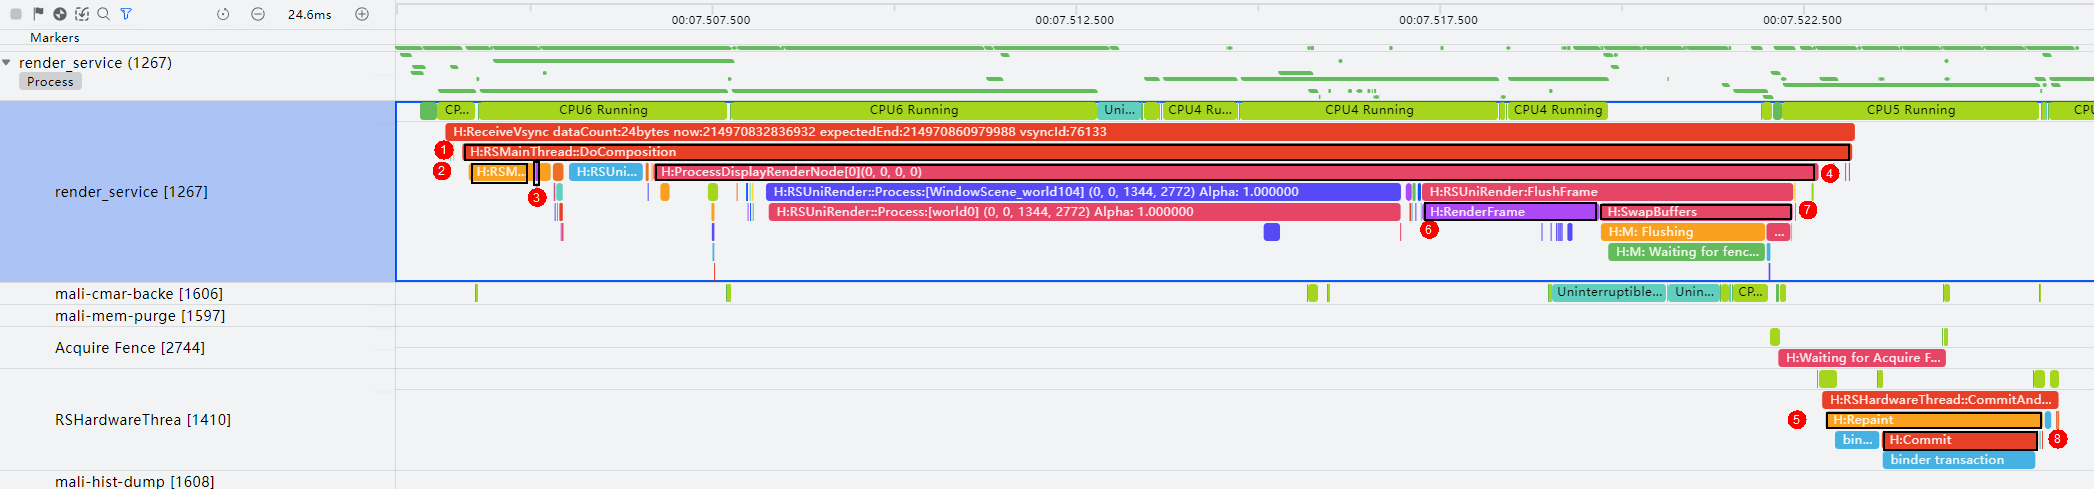
The following table describes each part of a trace.
No. | Trace | Description |
|---|---|---|
1 | RSMainThread::DoComposition | Composites the layers of nodes in the rendering tree. |
2 | RSMainThread::ProcessCommand | Processes app instructions. |
3 | Animate | Processes the animation. |
4 | ProcessDisplayRenderNode[x] | Performs drawing on a single display. |
5 | Repaint | Performs drawing by the hardware synthesizer. |
6 | RenderFrame | Performs drawing by the GPU. |
7 | SwapBuffers | Refreshes the display buffer. |
8 | Commit | Presents the drawing result on the display. |
[h2]Identifying Lazy Loading Rendering Processes Using Traces
Lazy loading is implemented using LazyForEach, which iterates over provided data sources and creates corresponding components during each iteration. When LazyForEach is used in a scrolling container, the framework creates components as required within the viewpoint area of the scrolling container. When a component slides out of the visible area, the framework destroys the component to reduce memory usage.
The following figure shows the trace lane graph of a frame during lazy loading.
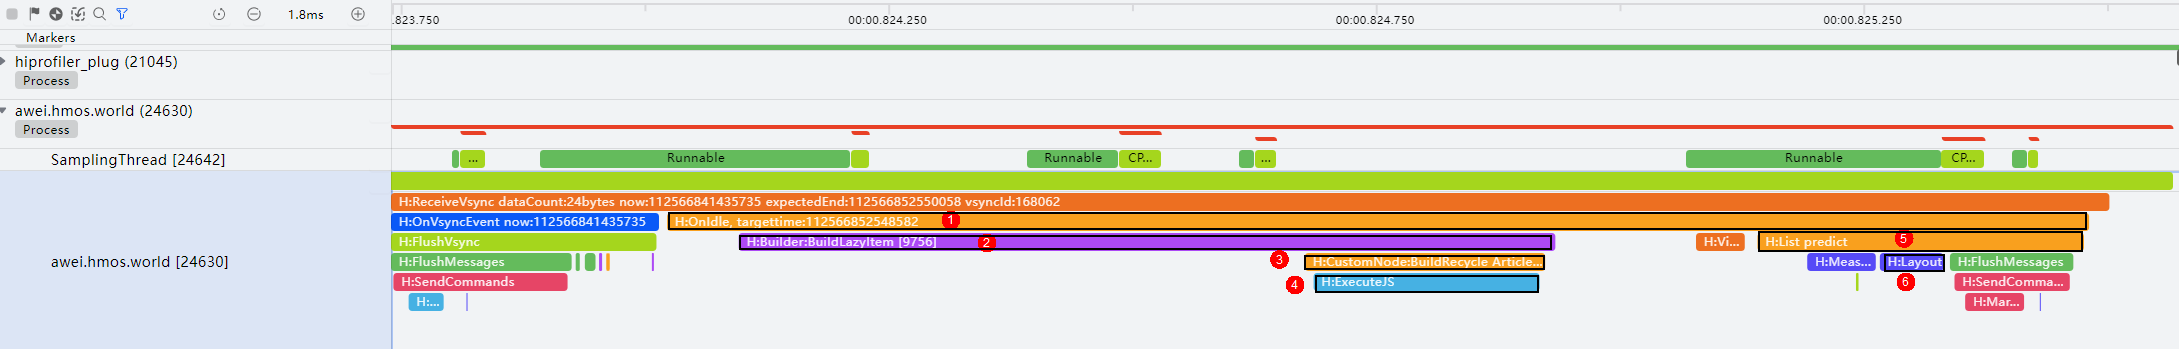
No. | Trace | Parameter | Description |
|---|---|---|---|
1 | OnIdle, targettime:%" PRId64 " | Timestamp, before which the task is completed. | In the idle event loop, the framework checks whether there are new events to be processed. If yes, the task scheduler is added to the UI thread and executes the predicted task. |
2 | Builder:BuildLazyItem [%d] | Index of the item to be created. | Builds an item when needed and caches it. |
3 | CustomNode:BuildRecycle %s | Name of the JS view. | Triggers rendering recycling. |
4 | ExecuteJS | Executes JS code. | |
5 | List predict | Adds a predicted layout task. | |
6 | Layout | Completes the layout of the current frame node. |
[h2]Adding Custom Trace Information
You can use HiTraceMeter to track custom traces in light of service requirements. For details, see Using hiTraceMeter (ArkTS/JS) and Using HiTraceMeter (C/C++).
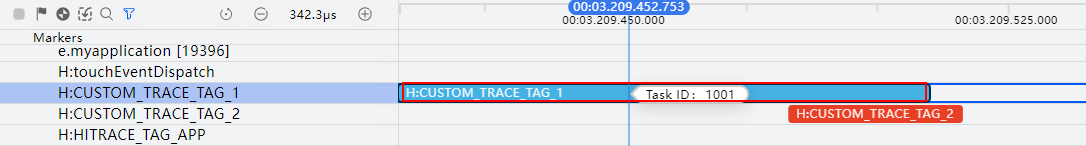
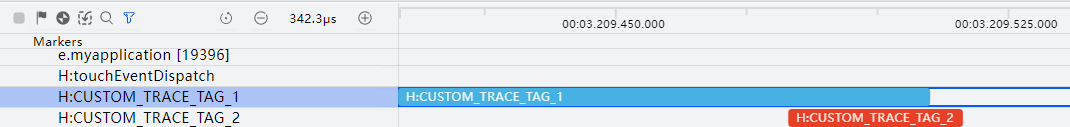
After adding custom traces, you can view it on the SmartPerf-Host debugging tool. Custom trace information is displayed as an independent lane in the corresponding process. The following figure shows two lanes that record the duration between the calls to startTrace and finishTrace. The figure records the durations of CUSTOM_TRACE_TAG_1 and CUSTOM_TRACE_TAG_2.
Example of a custom trace
Example of a custom status value